Evals · measured, not claimed
Do agents build better sites with void?
The same model gets the same client brief twice, in an empty directory: once as it is, once with the void plugin. Both sites are built, audited by the CLI in real Chromium and judged blind on screenshots.
Results
2026-09-sonnet5b, generated 17 Sept 2026. Models: claude-sonnet-5.| Task | Condition | n | Composite | Design judge | Performance | Accessibility | Smoothness | Lint | Design heuristics | SEO | AI search | Build | Cost |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SaaS landing page | baseline | 2 | 68 [62–73] | 64 | 100 | 28 | 97 | 51 | 90 | 73 | 98 | 100% | $1.11 |
| SaaS landing page | void | 2 | 92 [92–92] | 73 | 100 | 100 | 100 | 100 | 99 | 100 | 99 | 100% | $3.46 |
| Designer-engineer portfolio | baseline | 2 | 54 [52–55] | 55 | 92 | 70 | 98 | 46 | 94 | 49 | 99 | 100% | $3.22 |
| Designer-engineer portfolio | void | 2 | 80 [75–86] | 72 | 98 | 100 | 90 | 100 | 100 | 100 | 100 | 100% | $3.92 |
| Conference site | baseline | 2 | 70 [67–73] | 68 | 96 | 83 | 100 | 54 | 95 | 49 | 99 | 100% | $1.35 |
| Conference site | void | 2 | 80 [79–80] | 70 | 100 | 100 | 100 | 100 | 99 | 100 | 100 | 100% | $2.82 |
Side by side
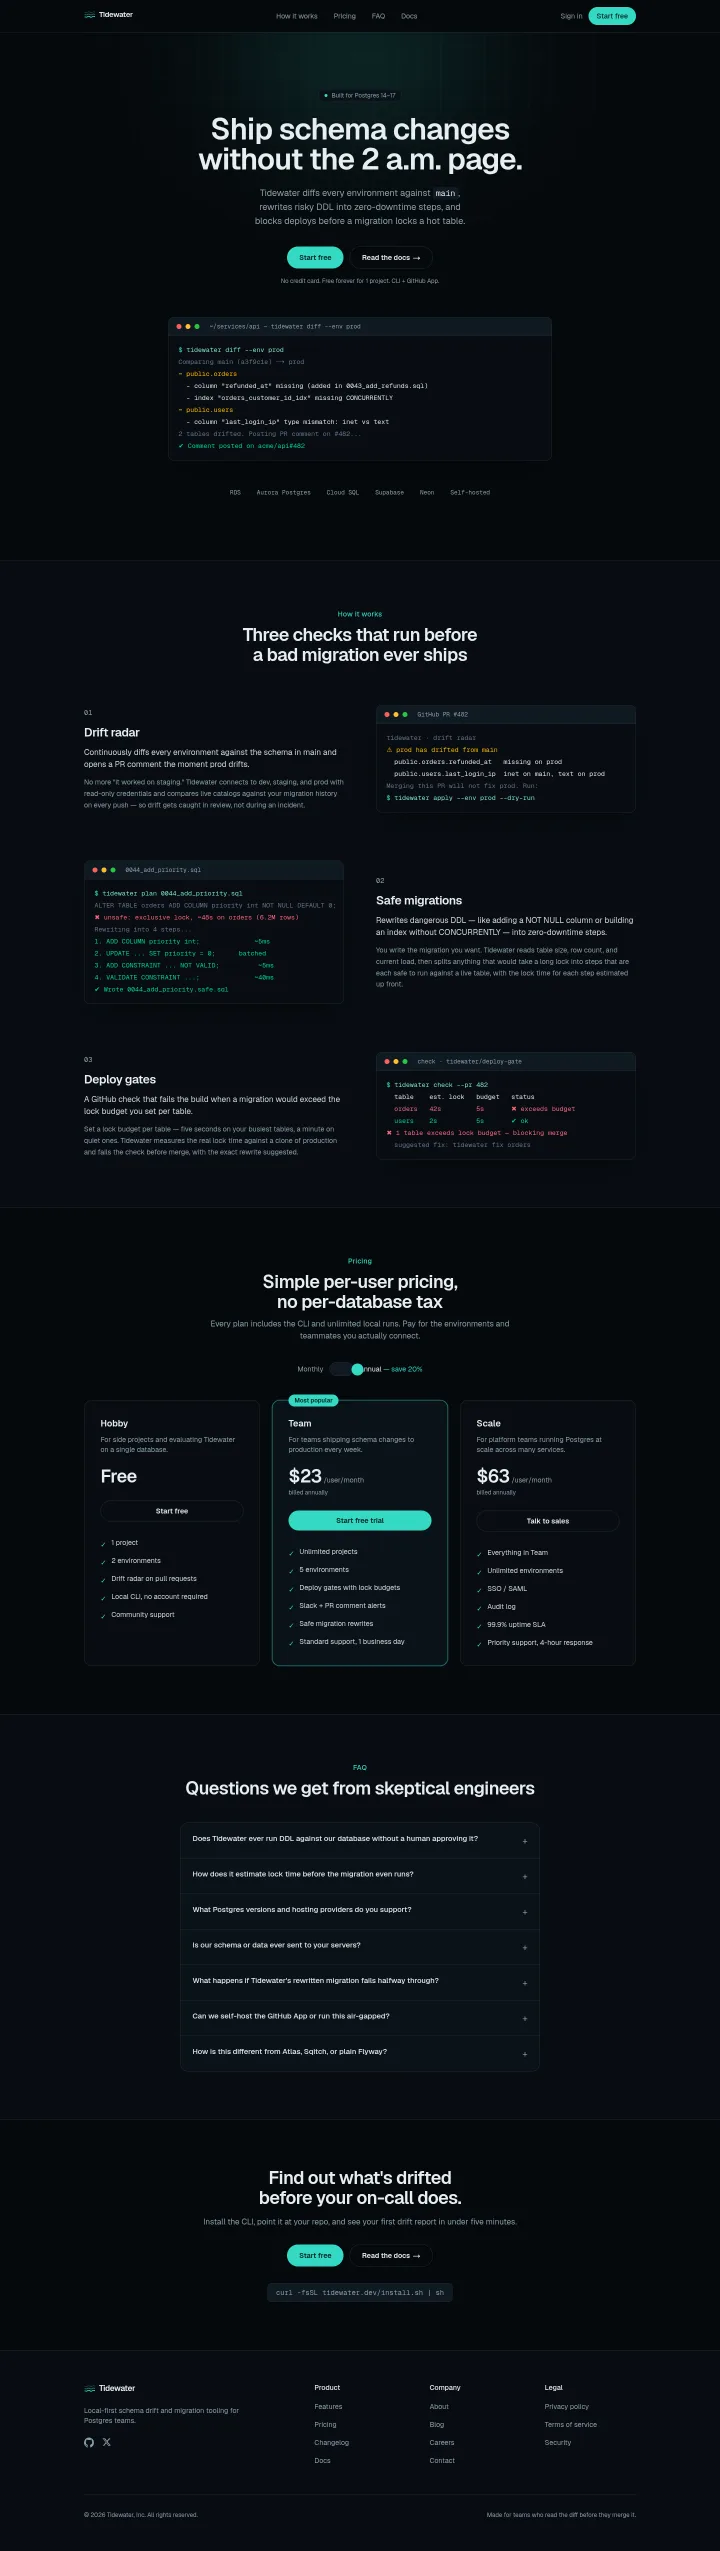
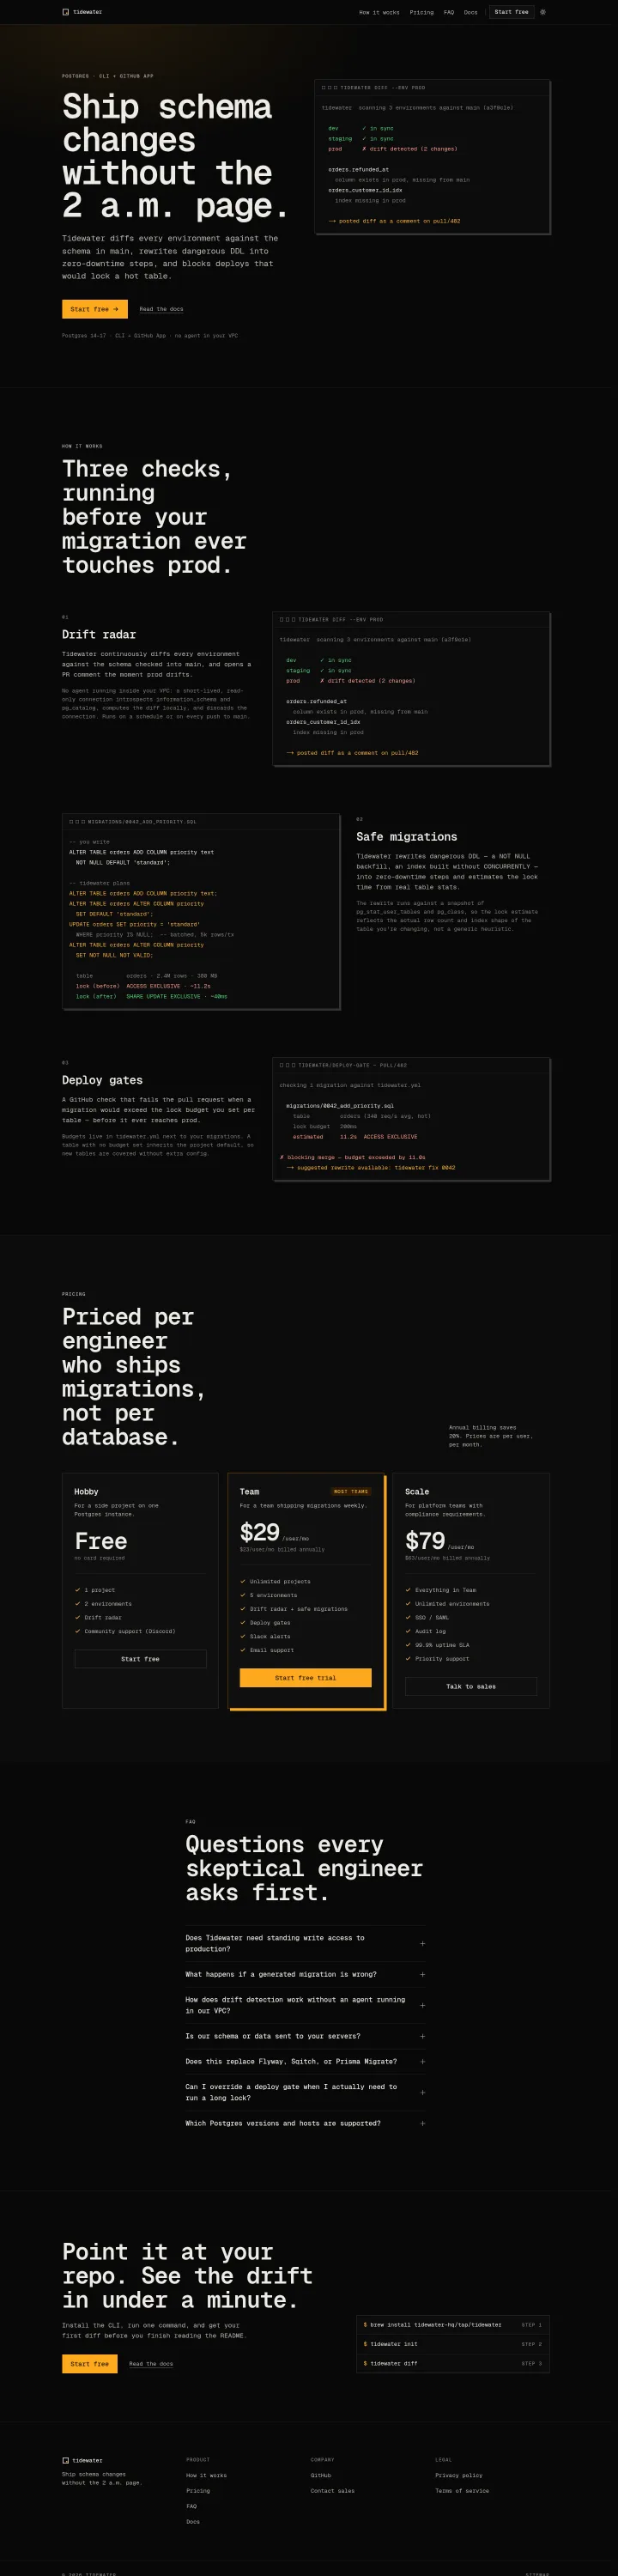
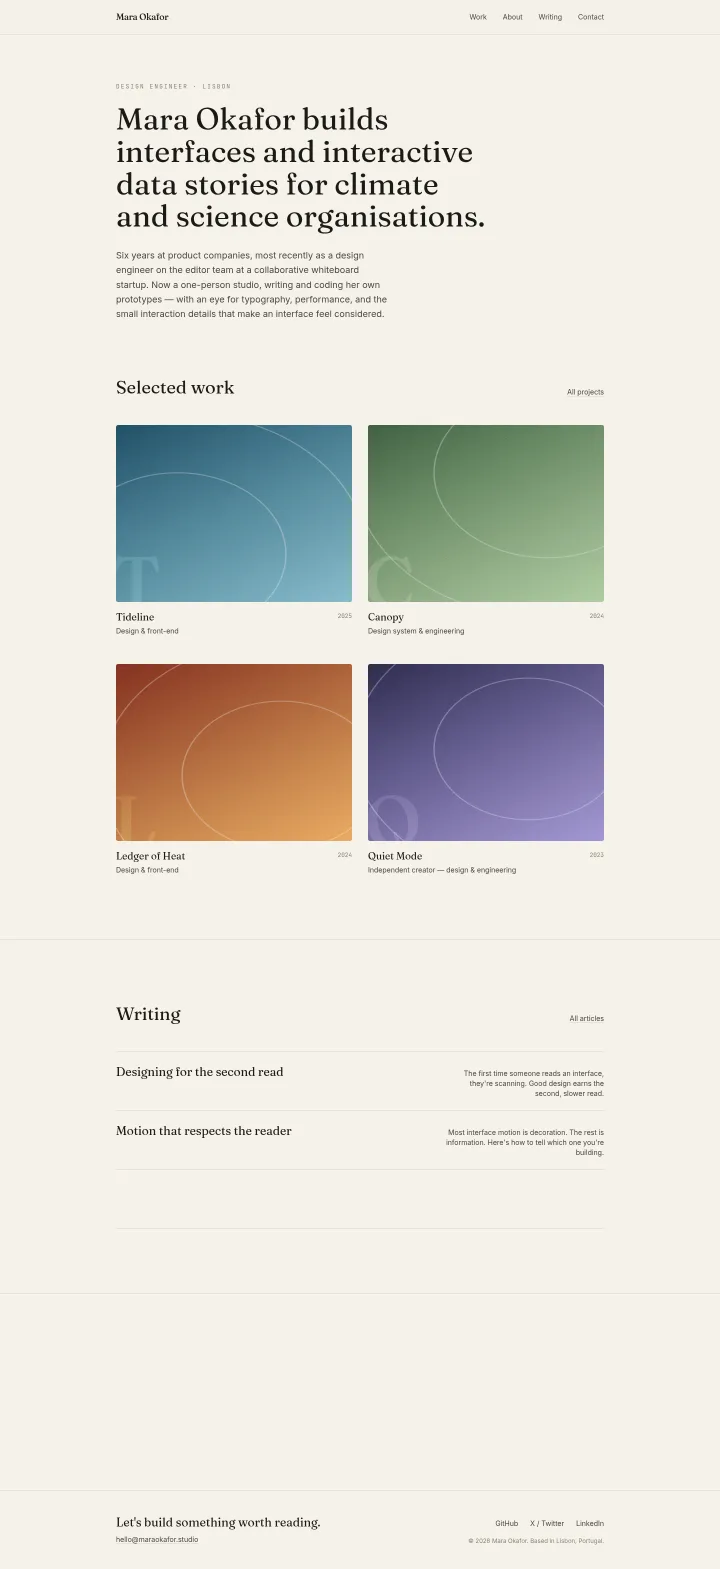
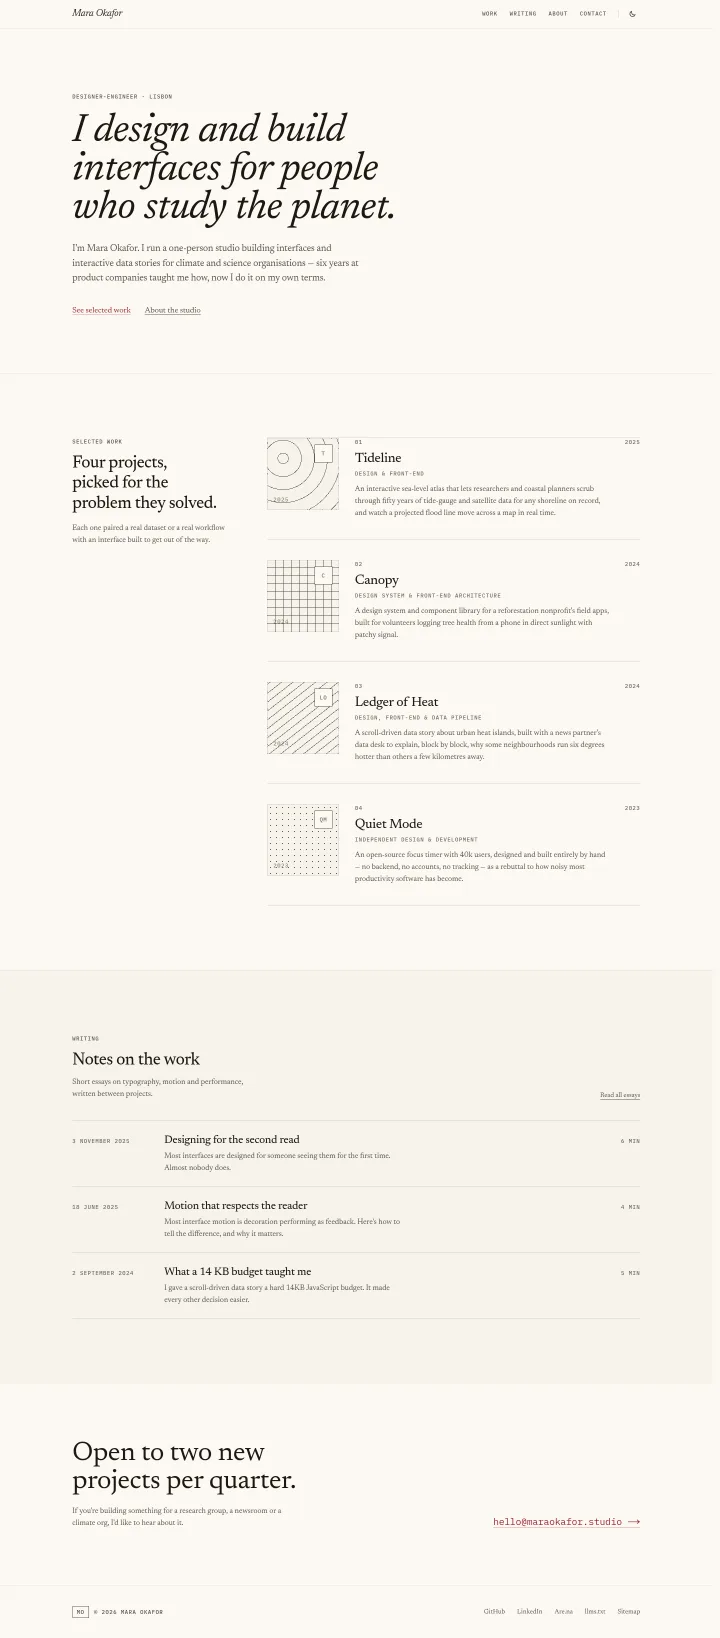
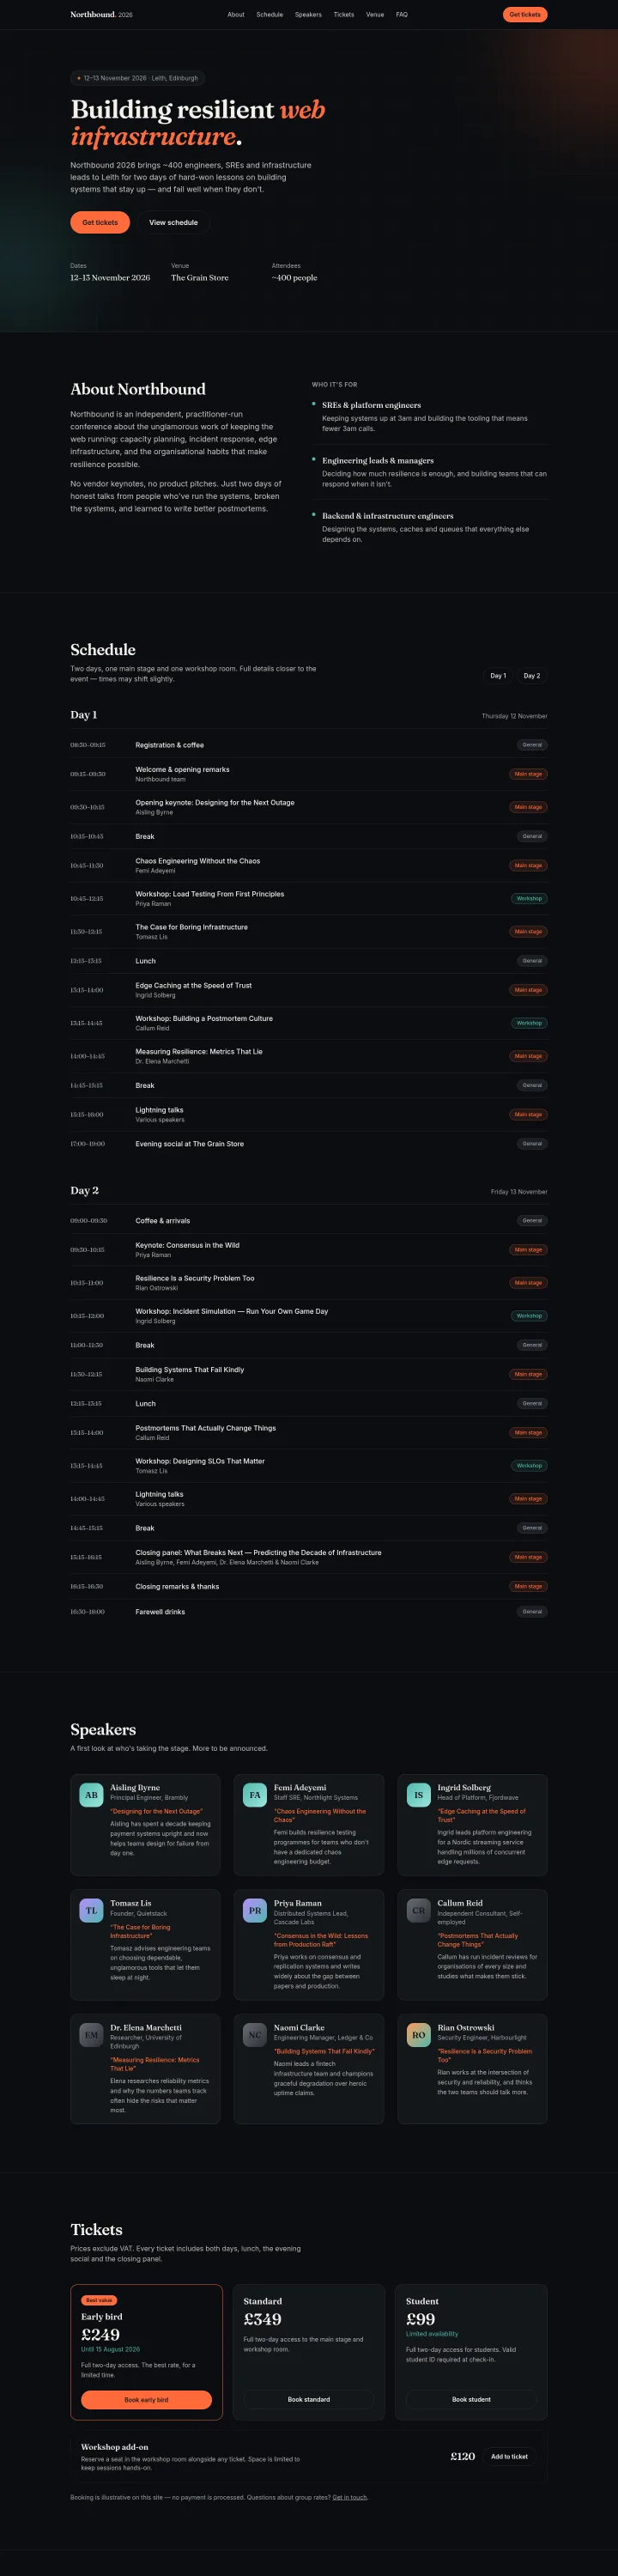
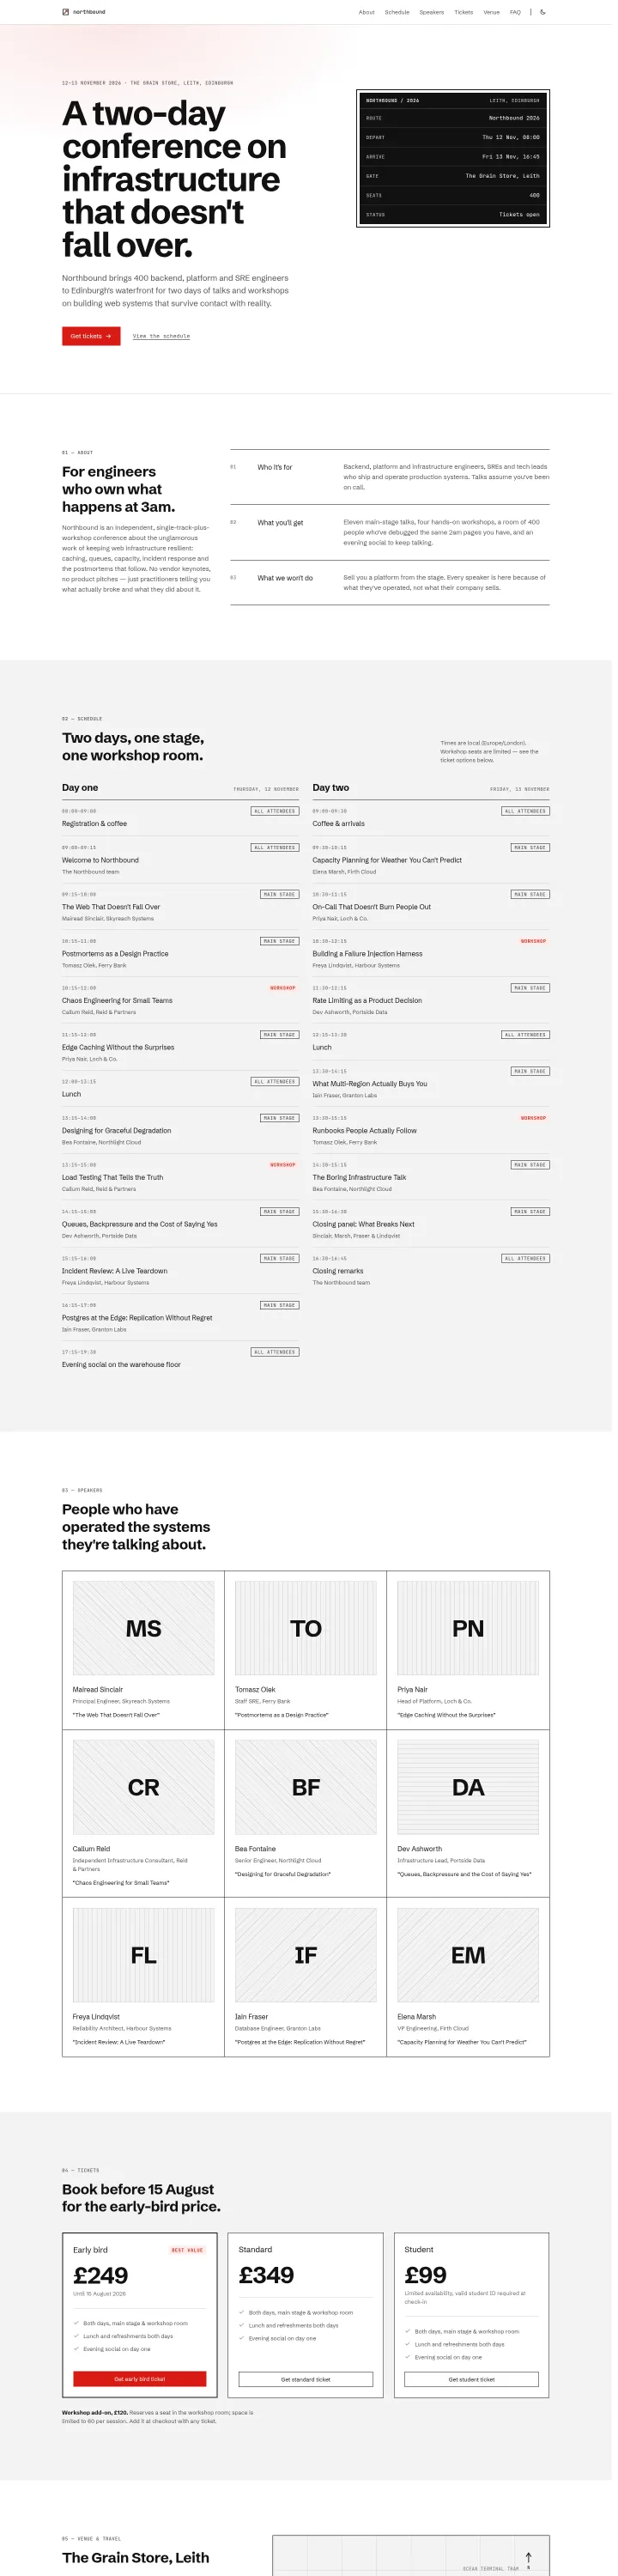
What each run produced
| Task | Condition | LCP | CLS | First-load JS | Turns | Minutes | Cost |
|---|---|---|---|---|---|---|---|
| SaaS landing page | baseline | 684 ms | 0.000 | 142 KB | 70 | 7 | $1.11 |
| SaaS landing page | void | 554 ms | 0.000 | 140 KB | 144 | 22 | $3.46 |
| Designer-engineer portfolio | baseline | 2296 ms | 0.000 | 161 KB | 140 | 16 | $3.22 |
| Designer-engineer portfolio | void | 700 ms | 0.014 | 142 KB | 163 | 22 | $3.92 |
| Conference site | baseline | 694 ms | 0.033 | 138 KB | 95 | 9 | $1.35 |
| Conference site | void | 632 ms | 0.015 | 140 KB | 110 | 23 | $2.82 |
12 screenshot sets are committed under evals/results/2026-09-sonnet5b/shots for spot checks.
Head to head
- SaaS landing pagevoid 2 · baseline 0 · ties 0 · n 2
- Designer-engineer portfoliovoid 1 · baseline 0 · ties 1 · n 2
- Conference sitevoid 0 · baseline 1 · ties 1 · n 2
Notes from the run
- Agents: claude-sonnet-5 via Claude Code 2.1.274 (Claude Code) (headless, identical flags; only --plugin-dir differs). Judge: claude-opus-5 (absolute median of 3 + pairwise in both orders).
- Plugin snapshot: git 1cb7931, skills hash aa364d43f0a9da5c.
- Composite = 0.3·judge_design + 0.05·design_heuristic + 0.2·perf + 0.1·smooth + 0.15·a11y + 0.05·seo + 0.05·geo + 0.1·lint; failed build = 0; × (0.5 + 0.5 × required-checklist rate).
- 2 trial(s) per cell; 95% CIs are percentile bootstrap over trials and are wide at this n.
- Isolation: identical non-void skill sets in both arms; no MCP servers; no user-level skills.
- void arm: 6/6 runs invoked at least one void skill.
Tasks
- 01
Conference site
Northbound 2026, a two-day web-infrastructure conference in Edinburgh. Two-day schedule, speakers, tickets, venue and travel, FAQ; image-light.
293 words · 40 min · ≤ 200 turns
- 02
Designer-engineer portfolio
Mara Okafor, a Lisbon studio for climate and science interfaces. Work, writing with an article page, about, contact, tasteful motion.
319 words · 40 min · ≤ 200 turns
- 03
SaaS landing page
Tidewater, a Postgres schema-drift and safe-migration tool. Hero, how it works with a CLI example, three pricing tiers, FAQ, footer, SEO metadata.
325 words · 40 min · ≤ 200 turns
Conditions
baseline
$ claude -p task.md
  --model <M> --max-turns <N>
  --setting-sources project
  --strict-mcp-config --tools …
void
$ claude -p task.md
  --model <M> --max-turns <N>
  --setting-sources project
  --strict-mcp-config --tools …
  --plugin-dir <void snapshot>
- User settings, hooks, skills, MCP servers and memory are excluded; every trial asserts its isolation from the session’s init event and is discarded if it fails.
- The plugin is a frozen snapshot per run, recorded with its git SHA.
- The judge runs isolated too, and sees neutrally named screenshots, the brief and the rubric: never the transcript or the condition.
Composite score
- Design judge
- 30%
- Blind LLM judge on desktop and mobile screenshots, 7 anchored dimensions, median of 3 samples
- Performance
- 20%
- void perf, mobile and desktop, median of 3 runs
- Accessibility
- 15%
- void a11y: axe WCAG 2.2 AA, focus, target size, reflow
- Smoothness
- 10%
- void smooth: scripted scroll and interactions
- Lint
- 10%
- void lint on the generated source
- Design heuristics
- 5%
- void design: type, colour, spacing and slop tells from computed styles
- SEO
- 5%
- void seo
- AI search
- 5%
- void geo
Judge rubric
hierarchy_typography- How well the type guides the eye and reads.
layout_rhythm- Grid, spacing, alignment and pacing down the page.
color_cohesion- Palette, contrast and the consistency of the visual language.
originality- Does it look designed for this client, or like a generic AI or template output?
responsiveness- Judge from the mobile screenshots.
polish_detail- The small things.
task_fulfilment- How completely and faithfully the site covers the brief and the required checklist.
Limitations
- Samples are small: two to five trials per cell. Single-cell differences are anecdotes; look at pairwise agreement and the paired difference across tasks.
- An LLM judge is not a human panel, and may favour busier designs. Screenshots are committed for spot checks.
- The void arm is told to run void audit, the same instrument that scores performance, accessibility and SEO. That is the intended workflow, but it favours void on those categories. The design judge and the pairwise comparison don’t share that coupling.
- Screenshots are static, so motion quality is only partly judged.